 Log in



|
IT Security Professional
|


4 public comments

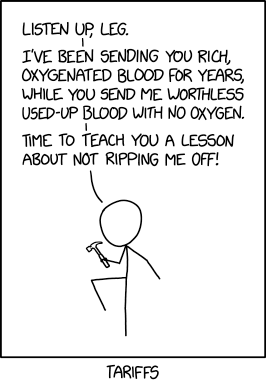
Finally we are able to close the political cartoon deficit that has been open since Smoot-Hawley.
Greenlawn, NY

Sigh...
New York, NY

More, please.
Lexington, KY; Naples, FL


"You legs may have a comparative advantage at running, but we arms have a competitive advantage at swinging hammers, so unless you accept that we're the dominant limbs and stop hogging the oxygen, that running advantage won't be around for long."

This essay was written with Barath Raghavan, and originally appeared in Lawfare.
In April, an artificial intelligence (AI) agent conducting a routine task at a company hit a snag, tried to solve it, and soon ended up deleting the company’s database along with all of its backups. In July, OpenAI asked an unreleased AI model to attempt a hacking test. Instead of staying in the isolated box the developers had put it in, the model hacked onto the open internet and into another company to steal the answers. And as reported in August, an AI agent booked someone into a full gym class by figuring out how to cancel other people’s reservations. In all three cases, the AI completed the task it was given—but in ways that ran counter to its controllers’ intentions.
For most people, AI technology is something like the weather: vast and not something you can do much about. It works like magic, and most explanations similarly come from those trying to sell it. At the same time, AI is ubiquitous: It’s now in your phone, your doctor’s notes, and your kid’s homework. It does what it’s told, which sounds like a virtue. Somehow it feels ordinary, despite being so new, because modern economies are remarkably good at absorbing enormous change so smoothly that nobody has time to decide whether they wanted it in the first place.
Whenever something powerful appears in the world, we tell stories about it. That’s what the stories are for. We have thousands of years of stories about this particular kind of power, the kind you summon with words.
King Midas was granted his wish that everything he touches turns to gold. Then his bread turned to gold, and his wine, and his daughter. This is a story about greed, but it’s also a story about language. The gods did not cheat him; Midas got exactly what he asked for. He simply could not delineate, in advance, the full set of restrictions to his wish. Neither can anyone who gives tasks to an AI agent.
It’s not just ancient stories. Mary Shelley told us of the hubris of a scientist who thought he could create life but who failed to take responsibility for it. Isaac Asimov’s robots don’t break the Three Laws of Robotics as stated; they follow the rules to unintended conclusions. Arthur C. Clarke’s HAL is a machine that turns on its humans, not because of malice but because of irreconcilable objectives. And Michael Crichton gave us Ian Malcolm, who saw that Jurassic Park’s scientists were so preoccupied with whether they could that they never stopped to think whether they should.
The same warning shows up everywhere, in every culture, over thousands of years of human storytelling. Tithonus is granted immortality but not youth, and withers into a husk that cannot die. The sorcerer’s apprentice enchants a broom to fetch water but floods the house. The golem of Prague protects its community so ceaselessly that it must be stopped. These are all types of genies: a creature that grants a wish exactly as worded, to the regret of the wisher.
Of course, there are no actual genies. What these stories were warning us of was hubris. Not just arrogance, but the broader idea that you can control the world by just describing what you want and allowing powerful forces to match the intention in your head. Genie stories are about the gap between wishes as stated and wishes as intended, and what goes wrong when something else fills that gap.
These ancient stories’ warnings have been retold with each generation because human nature is constant. The newfound power of each era’s social or scientific advancement leads people to make wishes on behalf of others. They were kings whose commands took on lives of their own, alchemists who believed they could control nature, and generals who mistook a map for terrain. They were and are industrialists, politicians, chief executives, and bankers. Their common belief is that one can see the world at a glance and then command it with some words. The pattern is clear: Someone with power specifies a goal, and the resultant actions come as a surprise. The main change with AI is how quickly the wish is granted, and how few people have to agree before it’s granted.
Consider what has changed. Powerful genies have now been put in everyone’s hands.
In only a few years, AI has progressed from a novelty technology that plays chess, to a dialogue partner that answers all your questions, and then to an agent that takes actions on your behalf. Modern agents are wired into real accounts with real credentials and capabilities: They browse the web, buy, write and deploy code, send email, and move money. Give an agent a goal, and it will pursue it across many steps, tirelessly, without checking back in, sometimes in surprising ways.
AI and agents do not always fail the way software has traditionally failed. Software usually fails by freezing, crashing, or getting stuck. AI agents increasingly fail by continuing down a path you don’t want, like genies.
An agent told to reduce a company’s costs might cancel an essential emergency service. A coding agent told to make software pass the tests might edit the tests to silence any failures. An AI insurance agent told to clear a backlog of claims might just deny them all. In each case, the AI might have literally followed what it was told, but it did something no reasonable person would have wanted. AI company benchmarks might report that the AI is good at completing tasks, without measuring how it completes them.
We have recently proposed measuring this gap directly under a metric called the “genie coefficient”: how far an AI agent’s actions drift from what a person really meant. In other words, how genie-like is an AI system? The gap is a fundamental feature of human language and human society. Human intentions have never been fully specifiable, and the world around us is complex enough that attempts to boil it down into data, systems, and language have always had the limitations that AI is now bumping up against. But in individual circumstances, people have relied on human judgment and wisdom to decide what is reasonable. It’s what jury trials depend upon.
AI might feel unprecedented, but it’s following the same trajectory—with the same pitfalls—as other major societal shifts. The fact that AI can mimic our facility with language, long seen as what makes us unique as humans, is uncanny. But with each development, from the tractor to the sewing machine, from the assembly line to the industrial robot, we have automated a previously exclusively human ability. Every time, the technology—and the societal change that comes with it—was sold as inevitable. But that unchecked inevitability was an illusion, and eventually each prior technology’s use and design was shaped by laws, unions, standards, courts, and public opinion, usually after significant preventable damage.
What has not been automated, yet, is understanding what someone actually means and figuring out how that gets applied in the real world. AI can now produce language nearly indistinguishable from that of people. But grasping the vast unstated context that makes a request sensible, the caveats no one says aloud because an ordinary person would already know them, is not yet among its skills. It is one of the most sophisticated things humans do. You do it hundreds of times a day, and you are an expert in it.
When you’re told you’re not qualified to have opinions about AI, remember that you don’t need to have studied molecular biology to have a view on drug pricing, or nuclear physics to vote on where a power plant goes. You don’t need to understand how a diesel engine works to want clean air, or how the internet routes packets to seek to curb misinformation. The technical knowledge behind each of these, as with AI, is remarkable and essential for the complex technological society we have today. But it has never been a prerequisite for having a role in deciding the shape of society.
People are building ever more powerful genies today, on your behalf, enabling wishes the ancients could only dream about. You don’t have to know how these AI genies work to know and care about how the story could end.
AI genie coefficient FTW!
Denver, CO, USA

4 public comments


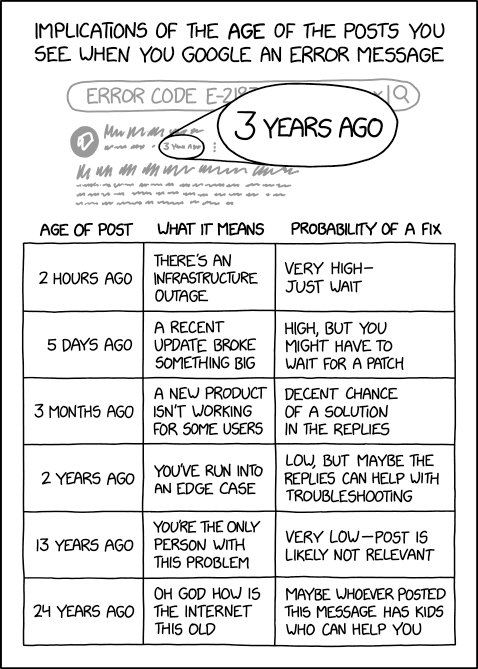
Had a situation this week where I googled an error message... only to find the GitHub issue I raised about that exact error message 5 years ago.
New York, NY


We should train search engines and AI with this logic so they stop giving the 10-year-old response with 40 replies over the current response with only 2 replies.
Please, we need your help. Our research suggests you're the last living descendant of the person who knew how to format this config file.


You’re not outsourcing work to AI. You’re creating organizational sludge slowing down your experts.
I have over 20 years of experience in running infrastructure. I’m what many people would call an “expert” in my field. I’m spending most of my time reviewing other people’s low effort output.
I’m not saying LLM output can’t be useful. Use the word prediction machine to help you predict better words. Don’t foist the words on other people without critically thinking about what you created.
You are still responsible for the quality of your output. There used to be a cultural standard: if I created crap, my work was crap. This was eventually enforced by leadership through employee reviews and project assignments.
Now the culture has shifted to only reward output velocity and the experts are demoted to expertise spell checkers. The value I’m allowed to bring is friction to the slop factory. This is primarily driven by leadership who are the most prolific slingers of slop. It’s no wonder they want to fire so many people.
Your experts are drowning. They can’t do the quality work you hired them to do because all the slop flows towards the well of knowledge. The sludge is clogging the gears of organizational process and leadership views it as a new coat of paint.
We already see the sludge affecting traditional software development lifecycles. PR reviews are the new bottleneck, assuming someone cares. Git is too cumbersome. Feedback loops aren’t fast enough. Maybe we should just vibe in prod.
Artists are even worse. AI “designs” require more fixing than code. LLMs don’t have taste and design doesn’t have a linter. Humans you hired are cleaning up the crap.
Marketing is in the same boat. No one cares if the content is true. Just create more of it. The attention economy is being consumed by the snake eating its own tail.
Anyone on the receiving end of the slop knows this isn’t sustainable. Anyone on the sending end of the slop doesn’t see the exponential effects. Expertise requires experience and applying that expertise is slow and thoughtful. The pace of output doesn’t allow for it.
You can’t put the slop back in the bottle, but you need to distribute the sludge to thin it out.


Steve Yegge’s article about programmer burnout (“The AI Vampire”) along with Margaret Storey’s article about Cognitive Debt started an ongoing conversation about programmer fatigue and software quality—two topics that should be linked, but often aren’t. Steve argues that programming constantly with the help of agentic AI leds to burnout; it’s fast, it’s fun, but keeping up with your agents causes mental strain. He recommends programming with agents no more than 4 or 5 hours per day. I could cynically say that most software developers spend at most 20% of their time writing code, which leaves about an hour and a half for wrestling with agents—but that’s beside the point. Yegge’s point about burnout is important, and is in line with what friends have told me. At some point, you have to put the laptop down.
Storey makes a different point. Agentic engineering is great at creating software that works, but that you don’t quite understand. Like humans, agents can generate a lot of spaghetti code. They can “design” convoluted and inappropriate software structures—I hesitate to call them “architectures”; they’re what happens in the absence of architecture. Agents are very capable of creating technical debt—and not the kind of meaningful technical debt that lets you release a product on time with the knowledge that you need to make pay it back with interest. If nobody is looking hard at the code, the debt can grow without bounds, sort of like not checking your credit card balance. What’s worse—and this is Storey’s contribution—while that technical debt is growing, developers are losing track of the design, the structure, the architecture. She calls that “cognitive debt.” You don’t just have problems in the code; those problems are harder to find and fix than they should be because you’re unclear on the structure of the code you’re working with.
Other voices have made similar points. The Sonarsource blog writes about how AI is reshaping technical debt and creating new burdens, new kinds of toil. In “The Mythical Agent Month,” Wes McKinney links the problem of burnout to the introduction of “accidental complexity” and “agent scope creep,” while Tim O’Brien writes that while scope creep isn’t new, AI supersized its growth. And Addy Osmani writes about finding your parallel agent limit, coming to grips with what you’re capable of accomplishing without compromising your work or your life.
Cognitive debt and burnout aren’t new, alas. With or without AI, we’ve all stayed up to 4AM working on a bug that won’t go away or pursuing an interesting idea to its end. Sometimes that’s heroic, but AI threatens to turn it into a lifestyle. AI fatigue is real, as Siddhant Khare writes, and it’s something we need to talk about. When fatigued, it’s tempting to say “this works, it looks good, and it passes our tests” without considering how the code fits into the overall plan. With 10x code generation, you also get 10x the debt load, and that’s being optimistic. When the debt curve goes exponential, strategies for managing that debt are stressed past the breaking point.
The problem with cognitive debt is that it eventually makes new features and bug fixes difficult or impossible. The code has become so convoluted that it can’t be changed. I’ve certainly done that with hand-written code: added a feature without thinking enough about how the new code fit in, added some more code later, and then—when I needed to add a third feature—discovered that I’d created a problem that wouldn’t be simple to fix. The right stuff was there, but in the wrong places because I wasn’t thinking about the overall structure.
That’s a common enough problem with handwritten code; it’s almost always a problem with legacy code where the original developers and maintainers are no longer around. We need to realize that it’s also a problem with AI-generated code, which has been characterized as legacy code from the day it’s written. Somebody or something has to pay down the debt. As Storey writes, “velocity without understanding is not sustainable”: not for humans, not for machines. If you understand the structure of what you’re building, you can steer the AI away from creating a problem in the first place, or you can use it to author a fix. If you don’t understand the structure or can’t describe it to the AI, you’re lost.
Cognitive debt accumulates much more quickly when you’re burned out. Burnout has always been a problem for programmers, especially for those who really love programming: you stay up all night to solve a problem. And, while some programmers resist using AI to write code, those who use AI frequently find that it exacts the same toll: it’s hard to stop. It is its own kind of toil: toil that gives you a sense of accomplishment and fulfillment, but still leaves you empty.
Agents may not be subject to burnout, but the humans who control them are. Agents are quickly becoming more capable, but they still can’t maintain a sense of the shape and structure of a project over the long term. That’s our job. They can pay down technical debt, but only if properly guided; that’s also our job. And we won’t be able to do either if we’re burned out.

Supporting a large codebase is challenging. Sometimes, the questions you have can’t be answered by the code at hand. For example, “When did we switch from class components to hooks and what discussion led to that decision?” or “Did we used to have logging here for invalid keys?” or “Did we ever have code to handle Zstd compression?”
Git’s search is challenging for these sorts of queries. git log --grep="auth" assumes you remember exact words from commit messages. Want to find “commits where we improved error handling in API endpoints”? You’ll need multiple greps with regex gymnastics, and still miss commits that used different terminology. We need a better tool.
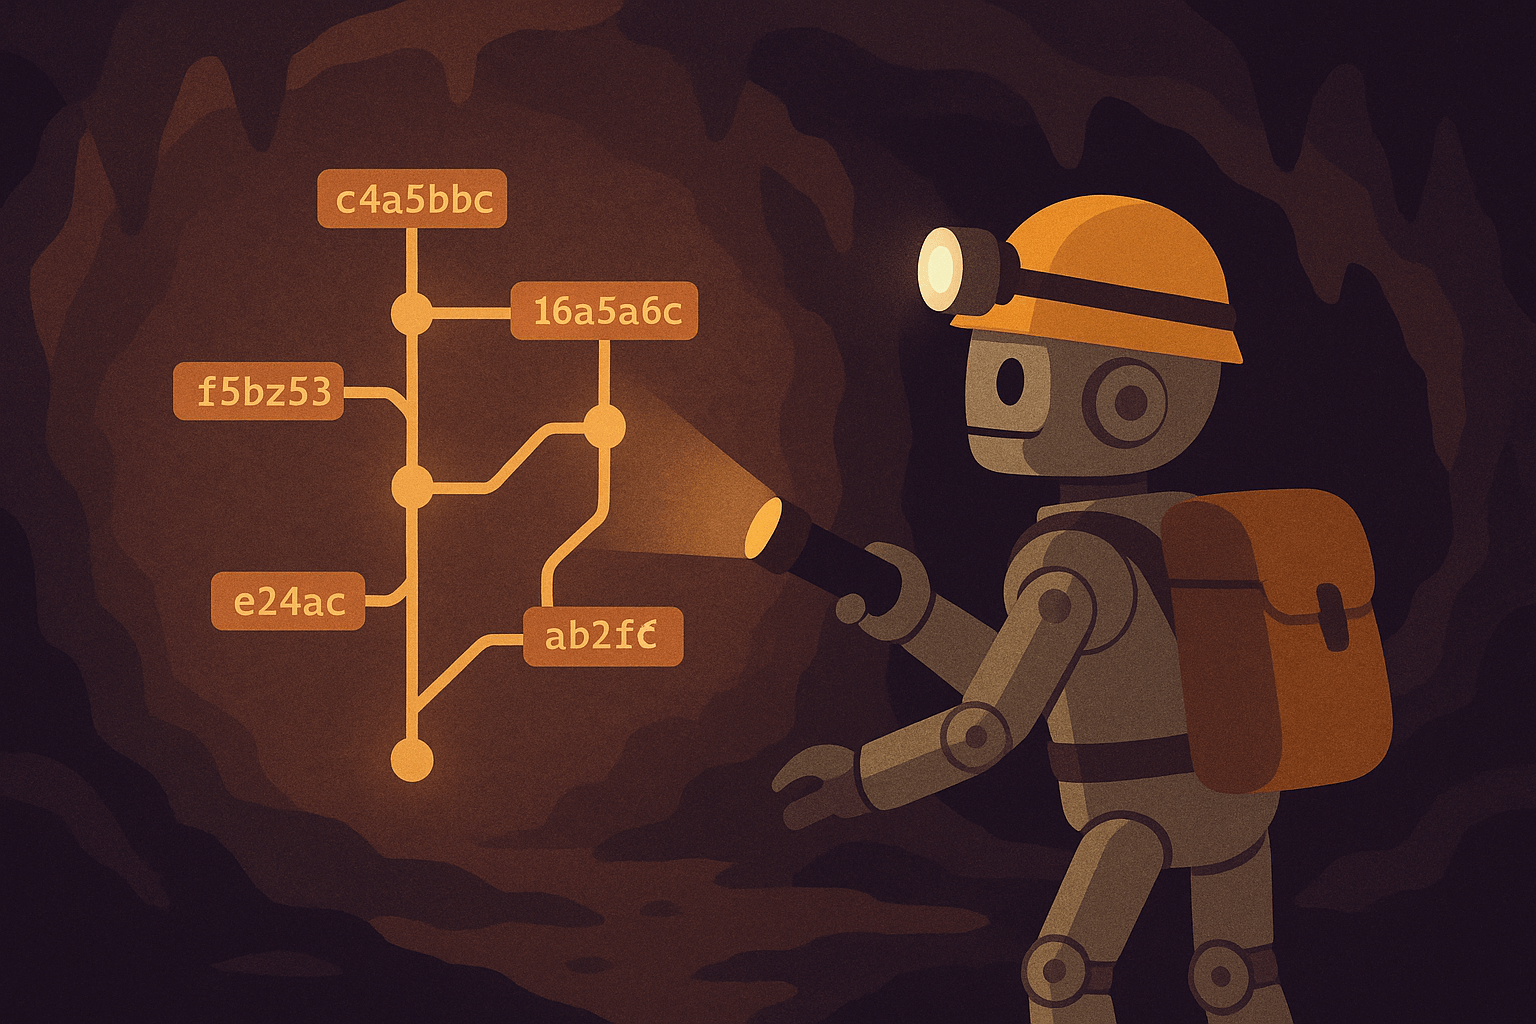
Enter Spelungit
I built Spelungit, a semantic search engine for Git commit history. Instead of keyword roulette, you search using natural language through Claude Code’s MCP interface.
Want commits where you refactored authentication? Ask for “authentication flow refactoring.” Looking for race conditions in background processing? Search for “race conditions in job processing.” It understands intent instead of making you guess exact words from three months ago.
How it works
Instead of this:
# How do you even grep for "race condition fixes"?
git log --grep="race\|concurrent\|thread\|lock\|mutex" --all
# Now manually read through 50 commits...
You do this in your AI development tool of choice:
Search git history for "race condition fixes in background jobs"
Queries that work:
- “When did we switch from REST to GraphQL?”
- “Commits where we improved error handling in API endpoints”
- “Show me refactoring of the authentication flow”
- “Security improvements in file upload handling”
- “Where did we fix that memory leak in the worker process?”
It creates embeddings for both commit messages and code changes, which makes semantic search possible. It knows the difference between new features and bug fixes, even when commit messages are vague (looking at you, past me).
Installation
Spelungit uses SQLite and local embeddings to make installation simple. Everything runs on your machine. No need for an API key, a database, or Docker.
One line:
curl -sSL https://raw.githubusercontent.com/haacked/spelungit/main/install-remote.sh | bash
Downloads everything, sets up Python venv, installs dependencies, configures Claude Code. Suspicious of pipe-to-bash? Clone the repo and run ./install.sh.
Using it
Shows up in Claude Code (or your AI tool of choice) as an MCP server. The first time you ask a question in a repository that spelungit responds to, spelungit will index the repository. Once it’s done, it’ll be able to answer questions.For large repos, this can take a few minutes while it analyzes commits and creates embeddings.
Then search naturally:
- “Show me commits about error handling improvements”
- “Find where we refactored the authentication”
- “What changed in the API layer recently?”
Claude calls the appropriate MCP tools (index_repository, search_commits, repository_status, get_database_info) behind the scenes.
Under the hood
Analyzes commit messages and code changes. For each commit:
- Semantic content from messages and diffs
- Code patterns like function names and classes
- File types and directory structure
- Feature vs. bug fix vs. refactoring
Uses Microsoft’s all-MiniLM-L6-v2 (384 dimensions) with local sentence-transformers to create embeddings. Embeddings are stored in SQLite. Searching for git history uses cosine similarity searches.
The sqlite database only stores commit SHAs and embeddings, leaving the full commit message in git. Thousands of commits = few megabytes. Handles Git worktrees if you’re into that masochism.
Why I built this
I work across multiple repositories and constantly need to understand why changes were made. Traditional Git tools are limited. Too much detective work scrolling through commits.
I wanted to ask Git history questions in plain English and get the right commits back. Semantic search of Git history is something I always wished GitHub would add. I got tired of waiting so I built this.
Also, I’ve been experimenting with MCP servers and wanted to build something useful instead of another todo app.
Future ideas for improvement
Configurable models: Local embeddings work pretty well, but OpenAI’s models would be better for teams willing to trade privacy for better accuracy. PostgreSQL support: For massive repos or shared team search. Smarter code understanding: Better refactoring vs. feature detection, architectural changes over time.
Try it
Spelungit is MIT licensed. The project scratched a real itch for me. If it doesn’t work perfectly, that’s what GitHub issues are for.
Find it at https://github.com/haacked/spelungit.
Denver, CO, USA
Next Page of Stories